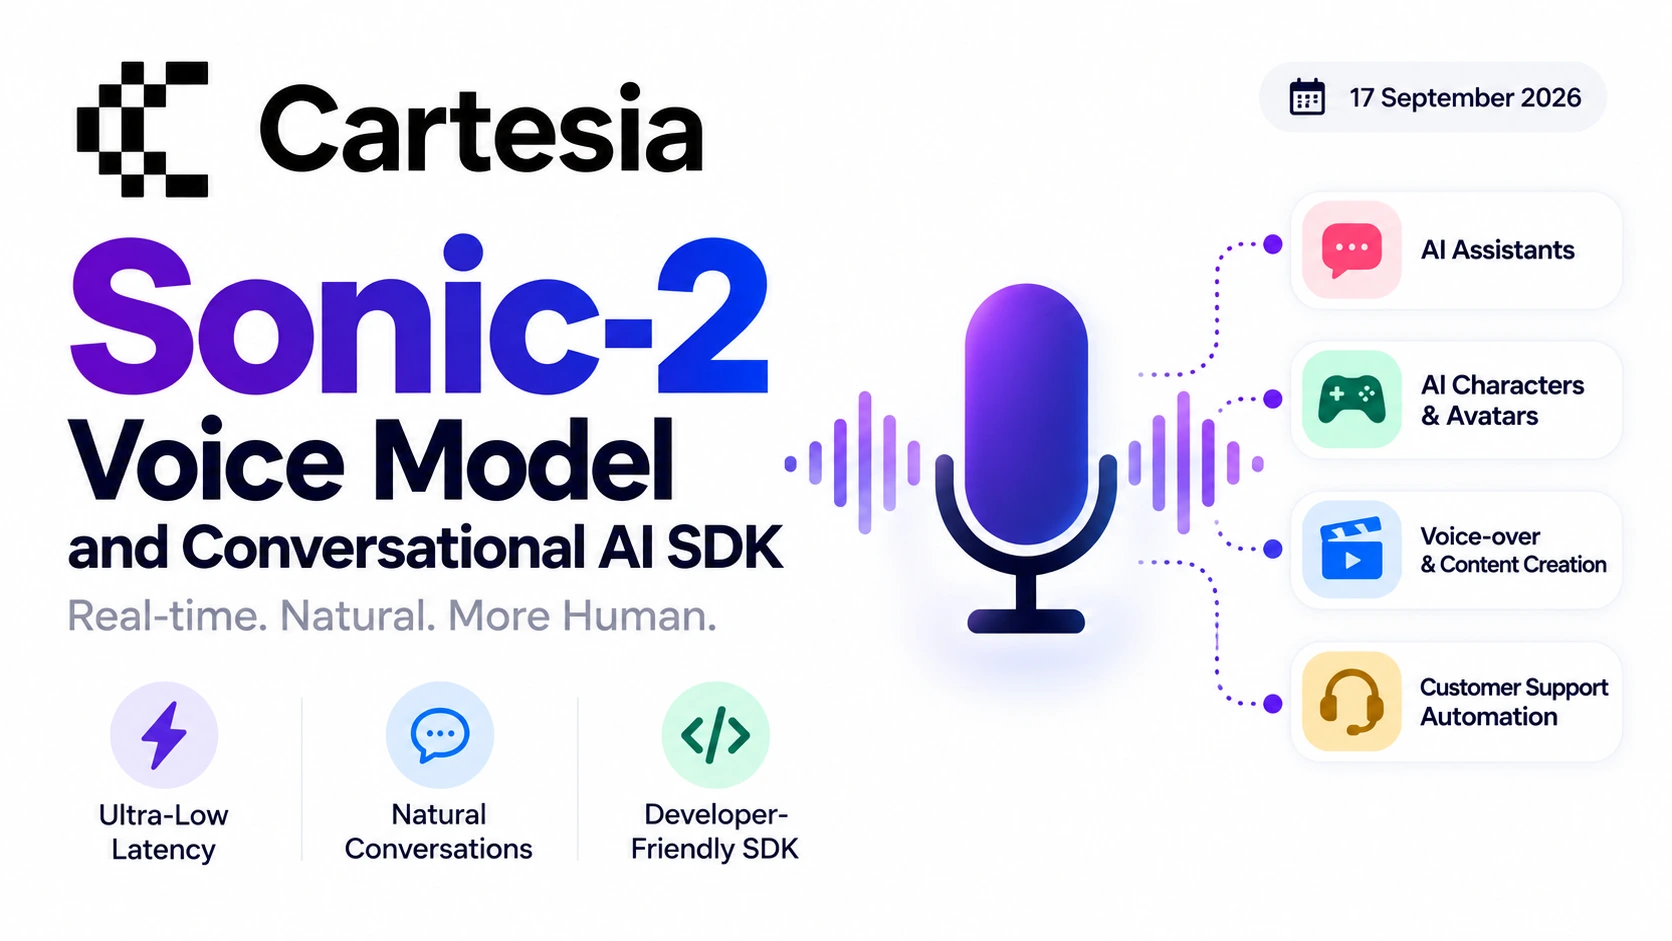
Real-time voice AI is becoming an important part of modern applications, from AI assistants and customer-service agents to interactive characters, voice-over tools, and conversational applications. One of the companies focused heavily on this area is Cartesia, whose Cartesia Sonic-2 Voice Model was designed around the demanding requirements of real-time speech generation.
Unlike conventional speech-generation systems that commonly rely on Transformer-based architectures, Cartesia built its Sonic family around State Space Models (SSMs). Cartesia describes SSMs as a foundation for low-latency, long-context reasoning and efficient processing at scale.
The significance of the Cartesia Sonic-2 Voice Model was its emphasis on generating audio quickly enough for interactive applications. Cartesia’s documentation states that Sonic 2 could stream the first byte of audio in approximately 90 milliseconds, making it suitable for conversational AI, dubbing, narration and AI-avatar applications.
What Is the Cartesia Sonic-2 Voice Model?
The Cartesia Sonic-2 Voice Model was a text-to-speech model developed for fast, natural-sounding speech generation.
Instead of waiting for an entire response to be generated before playback begins, streaming allows audio to be delivered progressively. This is particularly important for voice agents because even relatively small delays can make a conversation feel less responsive.
Cartesia’s documentation describes Sonic 2 as an ultra-realistic TTS model capable of streaming audio with very low first-byte latency.
This architecture is particularly relevant to developers building applications where users expect an immediate response.
Examples include:
- AI voice assistants
- Customer-service agents
- Interactive voice applications
- AI characters and avatars
- Video narration
- Voice-over production
- Real-time conversational systems
Why Low Latency Matters for Voice AI
When people communicate with another person, responses normally begin quickly. A voice AI system that pauses noticeably before responding can therefore feel unnatural.
The Cartesia Sonic-2 Voice Model was designed to address this challenge through streaming audio generation.
Cartesia’s documentation reported approximately 90ms first-byte streaming for Sonic 2.
This doesn’t mean an entire response is completed in 90 milliseconds. Rather, it refers to the time required for the system to begin delivering audio. Total response time also depends on factors such as the LLM generating the text, network conditions, speech processing and application architecture.
This distinction is important when evaluating real-time AI voice systems.
State Space Models Instead of Conventional Transformer Architecture
One of the more interesting technical aspects behind Cartesia’s technology is its use of State Space Models (SSMs).
Cartesia says its platform is built around SSMs as a foundation for low latency, long-context reasoning and efficiency at scale.
For developers, the practical goal is straightforward: process and stream speech efficiently enough that AI-powered conversations can feel responsive.
The architecture itself may not be something creators need to understand in detail. What matters to an application developer is how that architecture affects latency, streaming and the overall user experience.
How Cartesia Helps Voice Creators
The Cartesia Sonic-2 Voice Model can be particularly useful for creators who work with AI-generated audio and interactive media.
1. AI Video Narration
Creators producing YouTube videos, explainers and educational content can use AI-generated speech as narration.
A developer can combine a script-generation system with a TTS API and automatically generate narration for each scene.
2. AI Characters
Interactive characters need fast responses. A character that waits several seconds before speaking can break immersion.
Low-latency speech generation can help create more responsive AI characters.
3. Voice Assistants
Developers can combine an LLM with speech recognition and Cartesia’s TTS technology to create conversational assistants.
The basic architecture can look like:
User speaks → Speech-to-text → LLM → Cartesia TTS → Audio response
Cartesia also provides speech-to-text technology through its Ink family, creating a broader stack for developers building voice applications.
4. Real-Time Customer Support
Businesses can integrate voice AI into customer-service systems. An AI agent can receive a user’s request, process it through an LLM or business application, and return spoken responses.
5. AI Avatars
The Cartesia Sonic-2 Voice Model was also relevant to AI-avatar applications where speech needs to be generated continuously and quickly.
Cartesia Subscription Plans
Cartesia’s current pricing is important to understand because its platform has evolved beyond Sonic-2.
As of September 2026, Cartesia’s official pricing page lists Free, Pro, Startup, Scale and Enterprise plans. The current TTS offering listed on the pricing page is Sonic-3.6, rather than Sonic-2.
| Plan | Price | Included Credits |
|---|---|---|
| Free | $0/month | 20,000 credits/month |
| Pro | $5/month | 100,000 credits/month |
| Startup | $49/month | 1.25 million credits/month |
| Scale | $299/month | 8 million credits/month |
| Enterprise | Custom | Custom |
The Free plan includes text-to-speech and speech-to-text capabilities. Pro adds commercial use and instant voice cloning, while Startup adds professional voice cloning and organizations. Scale adds priority support and higher concurrency limits. Enterprise provides custom usage, volume pricing and additional business features.
Cartesia’s pricing page currently lists Sonic-3.6 for TTS and Ink-2 for speech-to-text.
Creators should therefore check the current pricing page before starting a new Sonic-2-based project, because Sonic-2 is no longer the main production model.
How to Build a Voice Application With Cartesia
Here is a simplified step-by-step workflow for creators and developers.
Step 1: Create a Cartesia Account
Visit Cartesia and create an account. You can start with the Free plan to explore the platform and API.
Step 2: Choose Your Voice Model
For a new project, check the currently supported Sonic model rather than automatically selecting Sonic-2.
Cartesia’s current documentation recommends migrating older Sonic-2 implementations to newer models where applicable.
Step 3: Select or Create a Voice
Choose a suitable voice for your application. Depending on your plan and requirements, Cartesia supports voice cloning and other voice customization capabilities.
Step 4: Generate Your Script
Prepare the text that your AI voice should speak.
For example:
“Welcome to our AI assistant. How can I help you today?”
For a more advanced application, an LLM can dynamically generate this text.
Step 5: Send the Text to Cartesia
Your application sends the text to Cartesia’s TTS API together with the selected model and voice.
Cartesia supports streaming approaches designed for real-time speech generation. Its documentation provides API resources for developers working with TTS.
Step 6: Stream the Audio
Instead of waiting for the entire audio file, the application can receive audio progressively and begin playback as the audio becomes available.
This is where the low-latency design of the Sonic family becomes particularly useful.
Step 7: Connect TTS With an AI Agent
For a conversational application, connect the TTS system to:
Speech Recognition → LLM → Cartesia TTS → User
The LLM handles reasoning and response generation, while Cartesia handles spoken output.
Step 8: Optimize the Conversation
Finally, test response latency, interruptions, voice quality and network performance.
The goal is not simply to produce high-quality speech but to create an interaction that feels responsive.
What Happened to Sonic-2?
This is an important point for anyone discovering the Cartesia Sonic-2 Voice Model today.
Cartesia’s official API-change documentation says Sonic-2 versions were deprecated beginning June 1, 2026. Some snapshots remain listed as stable for a reduced language set, while Cartesia recommends newer models such as Sonic-3.5 for migration.
This means Sonic-2 remains relevant from a technology and product-history perspective, but developers starting a new project in September 2026 should review Cartesia’s current model documentation rather than assuming Sonic-2 is the recommended production option.
Why Cartesia Matters for AI Creators
The larger significance of the Cartesia Sonic-2 Voice Model is its focus on the real-time voice experience.
For creators, AI voice technology isn’t only about making speech sound realistic. Speed matters too.
A voice can sound excellent, but if the system takes too long to respond, the interaction can feel artificial.
Cartesia’s approach combines fast streaming speech with an ecosystem designed for developers building conversational applications. Its current platform brings together speech generation, transcription and voice-agent capabilities.
That makes the technology relevant to:
- YouTube and video creators
- AI application developers
- Game developers
- Voice-agent startups
- Customer-service businesses
- AI-avatar creators
- Interactive storytelling projects
Final Takeaway
The Cartesia Sonic-2 Voice Model represented an important step toward low-latency, conversational AI voice experiences. Its State Space Model approach and streaming-focused design demonstrated how TTS could move beyond simply generating audio files toward powering interactive conversations.
However, the current Cartesia platform has moved forward. As of September 2026, Cartesia’s official documentation and pricing pages emphasize newer models, including Sonic-3.6, while documenting the deprecation of several Sonic-2 versions.
For creators and developers interested in building real-time voice applications, the underlying lesson remains highly relevant: fast first audio, streaming generation and tight integration between speech, AI reasoning and applications are becoming central to conversational AI.
Frequently Asked Questions
Sonic-2 was a text-to-speech model built for fast, natural-sounding speech generation, designed to stream audio progressively rather than waiting for a full response before playback.
Cartesia’s documentation reported approximately 90 milliseconds to stream the first byte of audio. This is the time to begin delivering audio, not the total response time — that also depends on the LLM, network conditions and application architecture.
Instead of a conventional Transformer-based architecture, Cartesia built the Sonic family around State Space Models (SSMs), which Cartesia describes as a foundation for low-latency, long-context reasoning and efficient processing at scale.
AI video narration, interactive AI characters, voice assistants, real-time customer support and AI avatars — anywhere fast, natural speech generation matters.
A basic architecture flows: user speaks → speech-to-text → LLM → Cartesia TTS → audio response. Cartesia also offers speech-to-text through its Ink family.
As of September 2026, Cartesia lists Free ($0/month, 20,000 credits), Pro ($5/month, 100,000 credits), Startup ($49/month, 1.25 million credits), Scale ($299/month, 8 million credits) and a custom Enterprise plan.
Free includes TTS and speech-to-text. Pro adds commercial use and instant voice cloning. Startup adds professional voice cloning and organizations. Scale adds priority support and higher concurrency limits. Enterprise offers custom usage and volume pricing.
No. Cartesia’s pricing page currently lists Sonic-3.6 for TTS and Ink-2 for speech-to-text. Sonic-2 versions were deprecated beginning June 1, 2026, with some snapshots remaining stable for a reduced language set.
Cartesia recommends migrating older Sonic-2 implementations to newer models such as Sonic-3.5, and advises checking current model documentation before starting a new project rather than assuming Sonic-2 is still the production option.
The application sends text to Cartesia’s TTS API with the selected model and voice, then receives audio progressively and begins playback as it becomes available, rather than waiting for the entire file to generate.